The first test: 6 hours of footage, 98 searches
Before anything else, we wanted to know whether ClipRecall AI can find the right clip from a few typed words, on security camera footage it has never seen. This is what happened, with every kind of miss shown.
The footage
We used public security camera footage that we are allowed to show: the MEVA dataset, made by Kitware Inc. and IARPA. The people in this footage are actors who agreed to be filmed. Kitware and IARPA are not ClipRecall customers and did not take part. Their footage is public, and is named here so you can check it.
| Clips | 72, each five minutes long |
| Hours of video | 6 |
| Cameras | 12: 7 outdoors and 5 indoors |
| Frames read | 108,077, five every second |
| Marks on people and vehicles | 627,404 |
| Sightings | 1,776 |
| Pictures kept | 6,563 |
| Light | Daytime only |
Finding people and vehicles
The footage comes with boxes that people drew around those taking part in an activity. We counted how many of those ClipRecall AI found. The answer depends mostly on how large the person is in the picture, which is 1,080 pixels high.
People found, by how tall they are in the picture
Vehicles found
Of the people and vehicles it found, 1,295 of 1,931 were kept as one sighting. The rest were split into two or more.
Searching
All 98 searches were written before any search was run. A search counts when a right clip is among the first five results. Beside ClipRecall AI we ran the plain method it has to beat: count the colours in the picture, with no AI at all.
Clothes and colours
40 searches, against about 155 sightings on every camera. The first result was right 22 times for ClipRecall AI, and 18 times for the colour count.
Vehicles
20 searches, against about 238 sightings on every camera. The first result was right 18 times for ClipRecall AI, and 7 times for the colour count.
Actions
38 searches taken from the footage’s own activity labels, each against the sightings of one camera.
What it got wrong, and one it got right
A green frame is a right result. A red frame is a wrong one.
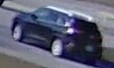
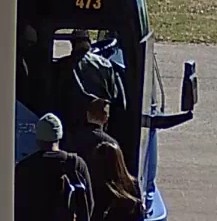
person opening a car bootThe first right clip came 74th, out of 109 sightings on one camera
 1, wrong
 2, wrong
 3, wrong
 4, wrong
 5, wrong
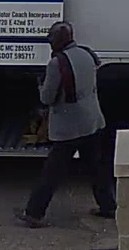 74th, right
The first results are cars. The labelled moment on this camera is a person at the luggage hold of a coach, which nobody would call a car boot.
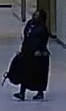
someone carrying something heavyThe first right clip came 48th, out of 124 sightings on one camera
 1, wrong
 2, wrong
 3, wrong
 4, wrong
 5, wrong
 48th, right
"Heavy" cannot be seen in a picture. The first results are people walking with empty hands. The right person carries a large bag.
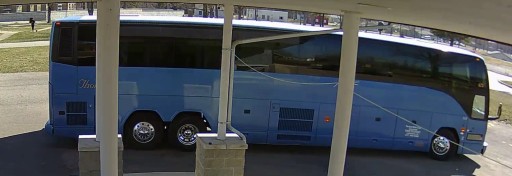
car dropping someone offThe first right clip came 96th, out of 109 sightings on one camera
1, wrong 2, wrong
 3, wrong
 4, wrong5, wrong
 96th, right
A drop off does not show in a still picture, and the labelled one on this camera was by a coach, not a car.
person in a red top carrying a backpackThe first right clip came 21st, out of 160 sightings on every camera
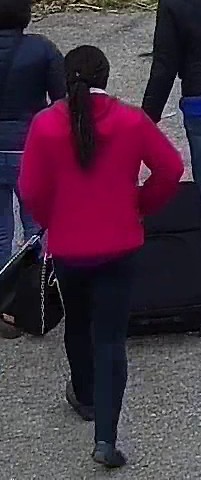 1, wrong
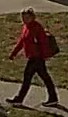 2, wrong
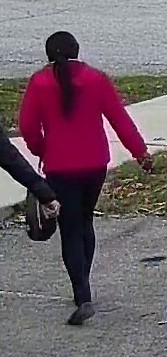 3, wrong
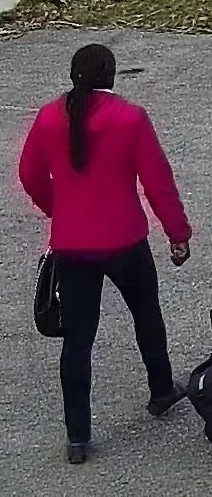 4, wrong
 5, wrong
Three of the first five wear bright pink, which ClipRecall AI treats as red. The other two wear red, but their marks call the thing they carry a bag, not a backpack.
person in a blue top carrying a boxThe first right clip came 68th, out of 159 sightings on every camera
 1, wrong
 2, wrong
 3, wrong
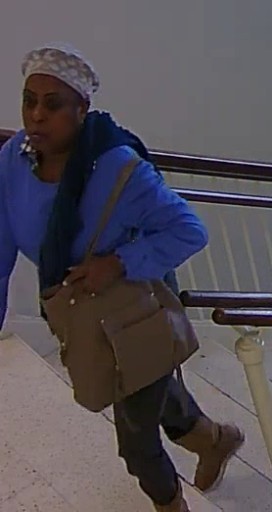 4, wrong
 5, wrong
ClipRecall AI found blue tops, but with bags, not boxes. It reads a colour better than the thing carried.
grey carThe first right clip came 2nd, out of 239 sightings on every camera
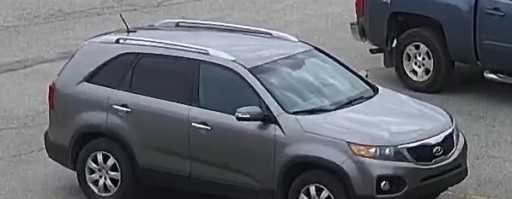 1, wrong
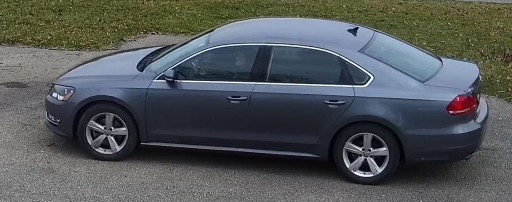 2, right
 3, wrong
 4, right
 5, wrong
Right in the first five, but not first.
person talking on a phoneThe first result is right, out of 223 sightings on one camera
 1, right
 2, right
 3, wrong
 4, wrong
 5, right
Three of the first five are right. The two marked wrong also show a hand raised to the head.
Every action search
Each search ran against the sightings of one camera. “Came” is the place of the first right clip in the results.
| Search | Kind | Sightings searched | Right ones among them | First right clip came | Chance alone |
|---|---|---|---|---|---|
| person talking on a phone | Shows in one picture | 223 | 11 | 1 | 23 in 100 |
| someone on a phone call | Shows in one picture | 141 | 5 | 2 | 17 in 100 |
| person looking at their phone | Shows in one picture | 223 | 31 | 2 | 53 in 100 |
| someone typing on a phone | Shows in one picture | 141 | 8 | 6 | 26 in 100 |
| person carrying a heavy object | Shows in one picture | 206 | 6 | 7 | 14 in 100 |
| someone carrying something heavy | Shows in one picture | 124 | 1 | 48 | 4 in 100 |
| person riding a bicycle | Shows in one picture | 223 | 2 | 1 | 4 in 100 |
| someone on a bike | Shows in one picture | 141 | 5 | 1 | 17 in 100 |
| person reading a paper | Shows in one picture | 126 | 2 | 11 | 8 in 100 |
| someone reading a document | Shows in one picture | 223 | 2 | 43 | 4 in 100 |
| person opening a door | Shows in one picture | 37 | 6 | 1 | 61 in 100 |
| someone at a door | Shows in one picture | 223 | 0 | Not found | 0 in 100 |
| person opening a car door | Shows in one picture | 206 | 8 | 3 | 18 in 100 |
| someone at a car door | Shows in one picture | 230 | 3 | 1 | 6 in 100 |
| person opening a car boot | Shows in one picture | 109 | 4 | 74 | 17 in 100 |
| someone at the open boot of a car | Shows in one picture | 206 | 9 | 1 | 20 in 100 |
| person loading things into a car | Shows in one picture | 109 | 3 | 71 | 13 in 100 |
| someone taking things out of a car | Shows in one picture | 216 | 5 | 4 | 11 in 100 |
| two people talking | Shows in one picture | 223 | 87 | 1 | 92 in 100 |
| people standing and talking | Shows in one picture | 63 | 26 | 1 | 94 in 100 |
| two people hugging | Shows in one picture | 223 | 7 | 3 | 15 in 100 |
| people embracing | Shows in one picture | 223 | 7 | 3 | 15 in 100 |
| person getting into a car | Needs movement | 206 | 5 | 4 | 12 in 100 |
| person getting out of a car | Needs movement | 216 | 5 | 10 | 11 in 100 |
| person coming in through a door | Needs movement | 63 | 25 | 3 | 93 in 100 |
| person going out through a door | Needs movement | 223 | 0 | Not found | 0 in 100 |
| person sitting down | Needs movement | 236 | 0 | Not found | 0 in 100 |
| person standing up from a seat | Needs movement | 230 | 1 | 83 | 2 in 100 |
| person picking something up | Needs movement | 230 | 3 | 12 | 6 in 100 |
| person putting something down | Needs movement | 230 | 1 | 28 | 2 in 100 |
| person handing something to another person | Needs movement | 109 | 2 | 3 | 9 in 100 |
| car turning | Needs movement | 223 | 18 | 3 | 35 in 100 |
| car reversing | Needs movement | 206 | 5 | 27 | 12 in 100 |
| car stopping | Needs movement | 223 | 8 | 1 | 17 in 100 |
| car driving off | Needs movement | 126 | 0 | Not found | 0 in 100 |
| car making a u turn | Needs movement | 223 | 2 | 14 | 4 in 100 |
| car dropping someone off | Needs movement | 109 | 3 | 96 | 13 in 100 |
| car picking someone up | Needs movement | 141 | 2 | 1 | 7 in 100 |
Three sizes of matcher
We ran the same searches with three sizes of the matcher. The numbers are searches with a right clip in the first five.
| Size | Clothes, of 40 | Vehicles, of 20 | Actions, of 38 |
|---|---|---|---|
| Small | 32 | 20 | 20 |
| Middle | 35 | 20 | 20 |
| Large | 32 | 20 | 20 |
No size was clearly better. The smallest did as well as the largest.
Can it say “nothing there”?
The matcher gives each result a score. We looked at 230 cases where the footage held no right answer at all. With a cut off low enough to keep every right first result, 36 of those 230 cases (16 in 100) still showed a wrong picture as if it were a match. So the score helps, but it cannot be trusted alone.
Who marked the right answers
For the action searches, the right answers are the boxes and activity labels that came with the footage. For clothes and vehicles, 223 pictures were marked for colour, kind and what was carried: 12 by a person and 211 by two AI helpers working apart, with their disagreements settled by an AI assistant. Where the person and the AI both named an answer, they agreed on 26 of 30. Marks made by AI are weaker evidence than a person’s, and we say so here so you can weigh the clothes and vehicle figures.
What this test covers
Daytime footage from one place in the United States, in full high definition. It holds no night video, no footage from Nigerian sites, and no keke or okada. The figures on this page are for this footage.
Video: "Multiview Extended Video with Activities" (MEVA) dataset by Kitware Inc. and IARPA, licensed under a Creative Commons Attribution 4.0 International License. Clips are shortened and resized.